
Grounding AI for SEO: How to Make Your Site a Source AI Models Trust
By Ghost Writr · · 13 min read
Your page can rank on page one and still never get mentioned by ChatGPT. That’s not a contradiction — it’s two different systems making two different decisions. Ranking is about relevance to a query. Grounding is about whether a model trusts your page enough to treat it as fact and repeat it to a user.
Here’s the direct answer: grounding is the process by which an AI model pulls in live content from the web — instead of relying solely on what it learned during training — to answer a question with current, verifiable information. When a model grounds a response, it retrieves candidate pages, checks them against the query, and decides which ones are reliable enough to cite or paraphrase. If you want AI assistants like ChatGPT, Gemini, Perplexity, or Google AI Overviews to find and cite your site, you need to structure content for that retrieval-and-verification moment specifically — not just for search rankings.
This article walks through what grounding actually is, when models use it versus answering from memory, how the major platforms differ, and the concrete steps that make a page grounding-ready.
What Grounding Actually Means
Grounding comes from Retrieval-Augmented Generation, or RAG — an architecture where a model doesn’t just generate an answer from its internal training, it first retrieves relevant documents from an external source (usually a live search index) and then generates a response using those documents as reference material.
There are two knowledge systems at play inside these tools, and understanding the difference is the whole ballgame.
Parametric knowledge is what the model learned during training — patterns baked into its weights from the dataset it was trained on. It’s frozen at the training cutoff and it doesn’t know about anything that happened after.
Grounded knowledge is retrieved live, at the moment of the query, from a search index or the web. It’s current, it’s sourced, and — critically for you — it’s citable, because the model can point to where it came from.
When a model grounds a response, it’s typically running something close to a live search: querying an index, pulling back candidate pages, and using them as source material for the answer it generates. That means your page isn’t competing to be memorized. It’s competing to be retrieved and then judged trustworthy enough to cite, in real time, every time the query comes up.
When a Model Grounds vs. Answers From Memory
Not every query triggers retrieval. Models make a judgment call, and understanding that judgment call tells you exactly which of your content is a grounding candidate and which isn’t.
Models tend to answer from parametric memory — no retrieval, no citation — when a fact is stable and well-established. Historical dates, basic definitions, settled scientific consensus: the model already “knows” these, and grounding them would be redundant.
Models tend to trigger grounding when:
- The query involves fresh or recent information — anything time-sensitive, where the training cutoff can’t be trusted to have the answer.
- The query is comparative — “best X for Y,” “X vs Z” — because these require current, specific, often opinionated synthesis across multiple sources rather than a single settled fact.
- The query is commercial — pricing, availability, local services — where the answer changes often enough that memorized knowledge would likely be wrong.
- The model’s internal confidence score is low — when it isn’t confident its parametric knowledge is sufficient or current, it reaches for retrieval as a check.
The practical implication: if your content answers a stable, timeless question, you’re competing with the model’s memory, and citation is less likely regardless of how well you write it. If your content answers something fresh, comparative, or commercial, you’re squarely in grounding territory — and that’s where structure, freshness, and clarity of sourcing actually move the needle.
Query Fan-Out: Why One Question Becomes Several Searches
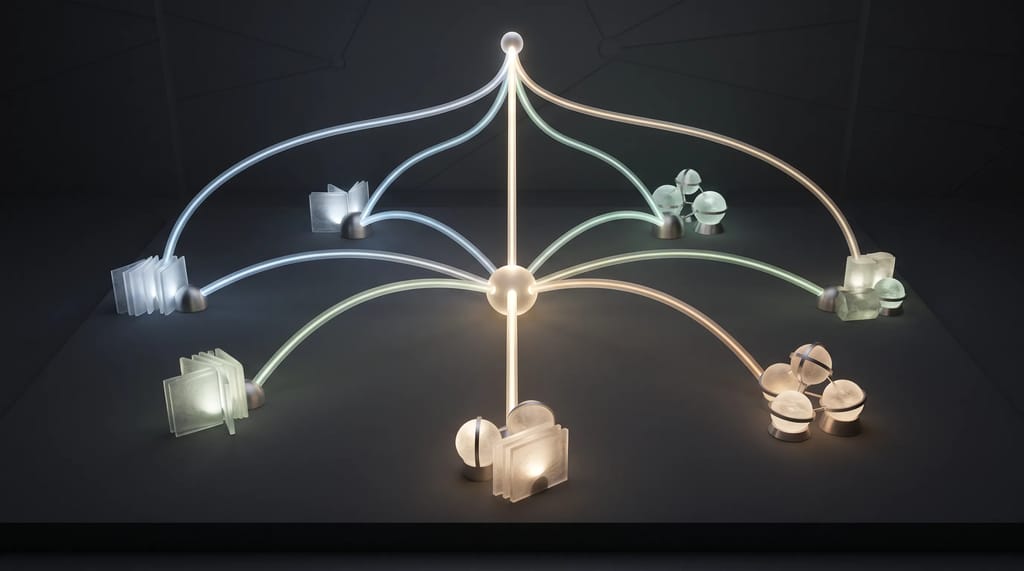
Here’s a mechanic that surprises a lot of people who assume “one query, one search.” Modern AI systems often don’t run a single search per question — they decompose a query into multiple sub-queries and run them concurrently, a process sometimes called query fan-out.
Ask an AI assistant “what’s the best CRM for a 10-person agency,” and behind the scenes it may be running several rewritten and related searches at once — pricing comparisons, feature breakdowns, reviews, alternatives — then synthesizing across all the retrieved pages into one answer.
This has a direct consequence for how you structure content: a single page that only answers the literal query you targeted is competing against a fan-out of five or six related searches. A page that comprehensively covers the entity — pricing, features, comparisons, use cases, limitations — gives the model more surface area to retrieve you across multiple sub-queries in that fan-out, not just one.
How Grounding Differs Across Platforms
Grounding isn’t one mechanism — each major platform implements it differently, and that changes what “citable” looks like in practice.
Google’s generative AI features are built to work with content that follows Google’s existing content and quality guidance for Search — the company is explicit that there’s no separate playbook for AI Overviews distinct from ranking well in organic search generally. Gemini can use dynamic retrieval to decide, query by query, whether grounding with live search is necessary at all.
OpenAI’s ChatGPT grounding behavior and Anthropic’s approach each have their own retrieval and citation logic, distinct from Google’s. Perplexity is built around citation-heavy, search-first answers as a core product behavior.
One distinction worth internalizing: being retrieved is not the same as being cited. A page can be pulled into a model’s context window as a candidate source and still not make it into the final visible citation — there’s a real gap between pages received and pages cited. That gap is why citation rate — how often a retrieved page actually gets named — matters more than raw retrieval as a measure of success.
The practical takeaway: don’t optimize for one platform’s quirks in isolation. Build content that’s structurally clean and unambiguous enough that any retrieval system can extract a clear answer, because you don’t control which model is doing the retrieving.
Traditional SEO Still Matters — Grounding Doesn’t Replace It
None of this makes classic SEO obsolete, and it’s worth being blunt about that because “AI search” hype tends to imply otherwise.
Rankings, backlinks, keyword relevance, technical SEO, and crawlability remain foundational — a page has to be indexed and technically accessible before it can be retrieved by anything, human or AI. Google’s own guidance for optimizing for generative AI features points back to the same fundamentals that drive good organic performance: helpful, reliable, people-first content, sound technical implementation, crawlable pages.
Think of it as layered, not replaced. Grounding is what happens after retrieval — but retrieval itself still depends on the page being crawlable, indexed, and relevant to the query in the first place. Skip the fundamentals and you never get to the grounding decision at all.
Content Quality and E-E-A-T Still Decide Trust
Grounding is a trust decision, and trust signals look a lot like what search engines have rewarded for years — first-hand experience, a clear point of view, and structure a machine can parse cleanly.
Commodity content — generic, derivative, saying what a hundred other pages already say — gives a retrieval system no reason to prefer you over a competitor covering the same ground. Content with a unique point of view, first-hand experience, and clean heading structure is easier for both crawlers and language models to extract a confident, attributable answer from.
Well-structured headings do double duty: they help human readers scan, and they give retrieval systems clean semantic boundaries to pull specific answers from without needing to interpret a wall of undifferentiated text.
Keyword Research Is Shifting Toward Conversation
Traditional keyword research optimizes for a handful of high-volume search terms. AI-driven search rewards something broader: covering the intent behind a topic across the many different ways a person might actually phrase a question to an assistant.
That means thinking in terms of personas and long-tail conversational queries — not just “best CRM software” but “what CRM should a 10-person agency with no dedicated ops person use.” A model synthesizing an answer is pulling from whichever page most directly and clearly answers the specific phrasing of the question, and conversational queries vary far more than typed keyword strings.
Practically: keep your primary keyword as the anchor for the page’s core topic, but build out the surrounding content to explicitly answer the adjacent questions a real person would ask in conversation — comparisons, edge cases, “what if” scenarios. That’s what feeds a query fan-out.
Grounding Pages: Structured, Factual, Single-Source-of-Truth Content
One of the most direct tactical responses to grounding is building dedicated grounding pages — pages designed explicitly to be a single, structured, factual source of truth about an entity: your business, a product, a service area.
A grounding page typically centralizes the facts a model needs to answer questions about that entity confidently: what it is, who it’s for, pricing structure, location, credentials, specifications — laid out in clean prose and reinforced with structured data. Schema markup (JSON-LD) tells a crawler explicitly what type of entity the page describes and what its key attributes are, reducing the ambiguity a model would otherwise have to resolve through inference.
The idea sometimes gets referred to as a Grounding Page Standard — the underlying principle is consistency and authority: one clear, well-marked-up page that answers the core factual questions about an entity, rather than the same facts scattered inconsistently across ten different pages. Inconsistent facts across your own site actively work against you — if your hours, pricing, or specs disagree from page to page, you’ve handed the model a reason to distrust all of them.
Local Signals Feed Grounding Too
For businesses with a physical or service-area presence, local signals are grounding signals. Google Business Profile data — hours, categories, services, reviews — feeds directly into how confidently an AI system can answer local, commercial queries about your business.
NAP consistency (name, address, phone number matching exactly across your website, your Google Business Profile, and other local citations) reduces the ambiguity a model faces when trying to confirm which entity a query is actually about. Structured markup like aggregateRating gives a model a clean, machine-readable signal about review sentiment instead of forcing it to infer sentiment from unstructured review text.
If your opening hours differ between your homepage footer and your Google Business Profile, that’s not a cosmetic inconsistency — it’s a trust signal working against you every time a local query gets grounded.
Measuring Whether You’re Actually Getting Cited
Traditional rank tracking doesn’t tell you whether AI assistants are citing you — you need a separate measurement layer.
Some teams now track Citation Share — the proportion of relevant AI-generated answers in which their content is actually cited, as distinct from how often it merely ranks. Google Search Console remains relevant here too, since it can surface data related to how your content performs in surfaces like AI Overviews, alongside traditional organic metrics.
Recall the retrieval-versus-citation gap covered earlier: a page can be received as a candidate by an AI crawler without ever being cited in the visible answer. That means a meaningful visibility check has two parts — are you being crawled and retrieved at all, and separately, are you actually the one getting named. If you’re invisible to AI crawlers entirely, that’s a technical access problem to fix first; if you’re retrieved but never cited, that’s a content trust and clarity problem. Treating them as the same problem wastes effort solving the wrong one.
Common Myths About Optimizing for AI Search
A few misconceptions are worth killing directly, because they lead people to optimize for the wrong thing.
Myth: domain authority alone gets you cited. Authority helps, but grounding decisions weigh structural clarity and factual verifiability heavily — a smaller site with an unambiguous, well-marked-up grounding page can out-cite a larger site whose facts are scattered and inconsistent.
Myth: backlinks are strictly required for AI citation the same way they’re required for ranking. Retrieval and citation decisions in generative AI systems are driven substantially by content structure and clarity at the point of retrieval, not solely by the link graph that got the page discovered.
Myth: longer content wins. Structure over size is the more accurate frame — a concise page that answers a question unambiguously, with clean headings and explicit facts, is easier for a model to extract from than a long page burying the answer in qualification and filler.
A Practical Checklist for Grounding-Ready Content
Pull it together into steps you can actually run through:
- Confirm crawlability first. No amount of grounding optimization matters if the page isn’t indexed and technically accessible.
- Identify your grounding-candidate topics. Prioritize pages answering fresh, comparative, or commercial queries — that’s where models are most likely to retrieve rather than rely on memory.
- Build or upgrade a grounding page per key entity — your business, core product, or service — as a single, structured source of truth with consistent facts.
- Add schema markup (JSON-LD) to make entity type and key attributes explicit rather than inferred.
- Audit fact consistency across your own site — pricing, hours, specs — and fix contradictions before anything else.
- Structure with clear, scannable headings that isolate discrete answers, not just narrative flow.
- Expand keyword thinking to conversational variants of your core topic, covering the intent across multiple likely phrasings.
- Align local data — Google Business Profile, NAP, reviews — if location or service area is part of your offering.
- Track citation, not just rank — check Search Console AI-surface data and monitor whether you’re actually being named in AI answers, not just retrieved.
- Re-audit periodically. Grounding-relevant facts (pricing, availability, specs) change; stale grounding pages lose the trust advantage they were built for.
FAQ
Is grounding the same thing as SEO? No. SEO is the practice of optimizing a page so it can be discovered, indexed, and rank well — it improves the odds, not a guarantee. Grounding is the separate decision a model makes about whether to trust and cite that page as a factual source once it’s been retrieved. You need both — ranking without grounding-readiness means you’re found but not cited.
Does every AI answer involve grounding? No. Models often answer stable, well-established questions directly from training data without retrieving anything live. Grounding is more likely for fresh, comparative, or commercial queries.
Do I need backlinks to get cited by AI models? Backlinks support traditional ranking and discovery, but citation within generative AI answers depends heavily on content structure and factual clarity at the point of retrieval. Don’t treat link-building as a substitute for fixing structural and factual clarity issues on the page itself.
What’s a grounding page, concretely? A single, well-structured page — reinforced with schema markup — that serves as the authoritative, consistent source of facts about a specific entity, like your business or a core product.
How do I know if I’m actually being cited by AI tools? Check Search Console data related to AI Overviews performance, and separately track whether your content is named in AI-generated answers versus merely retrieved as a candidate — those are two different outcomes worth measuring separately.